

News
NVIDIA released Nemotron 3.5 Transcribe, a free open-weight model that transcribes 40 languages and tells you who said what.
NVIDIA on Wednesday released Nemotron 3.5 Transcribe, a free, open-weight model that transcribes audio in up to 40 languages.
NVIDIA on Wednesday released Nemotron 3.5 Transcribe, a free, open-weight model that transcribes audio in up to 40 languages (TechCrunch).
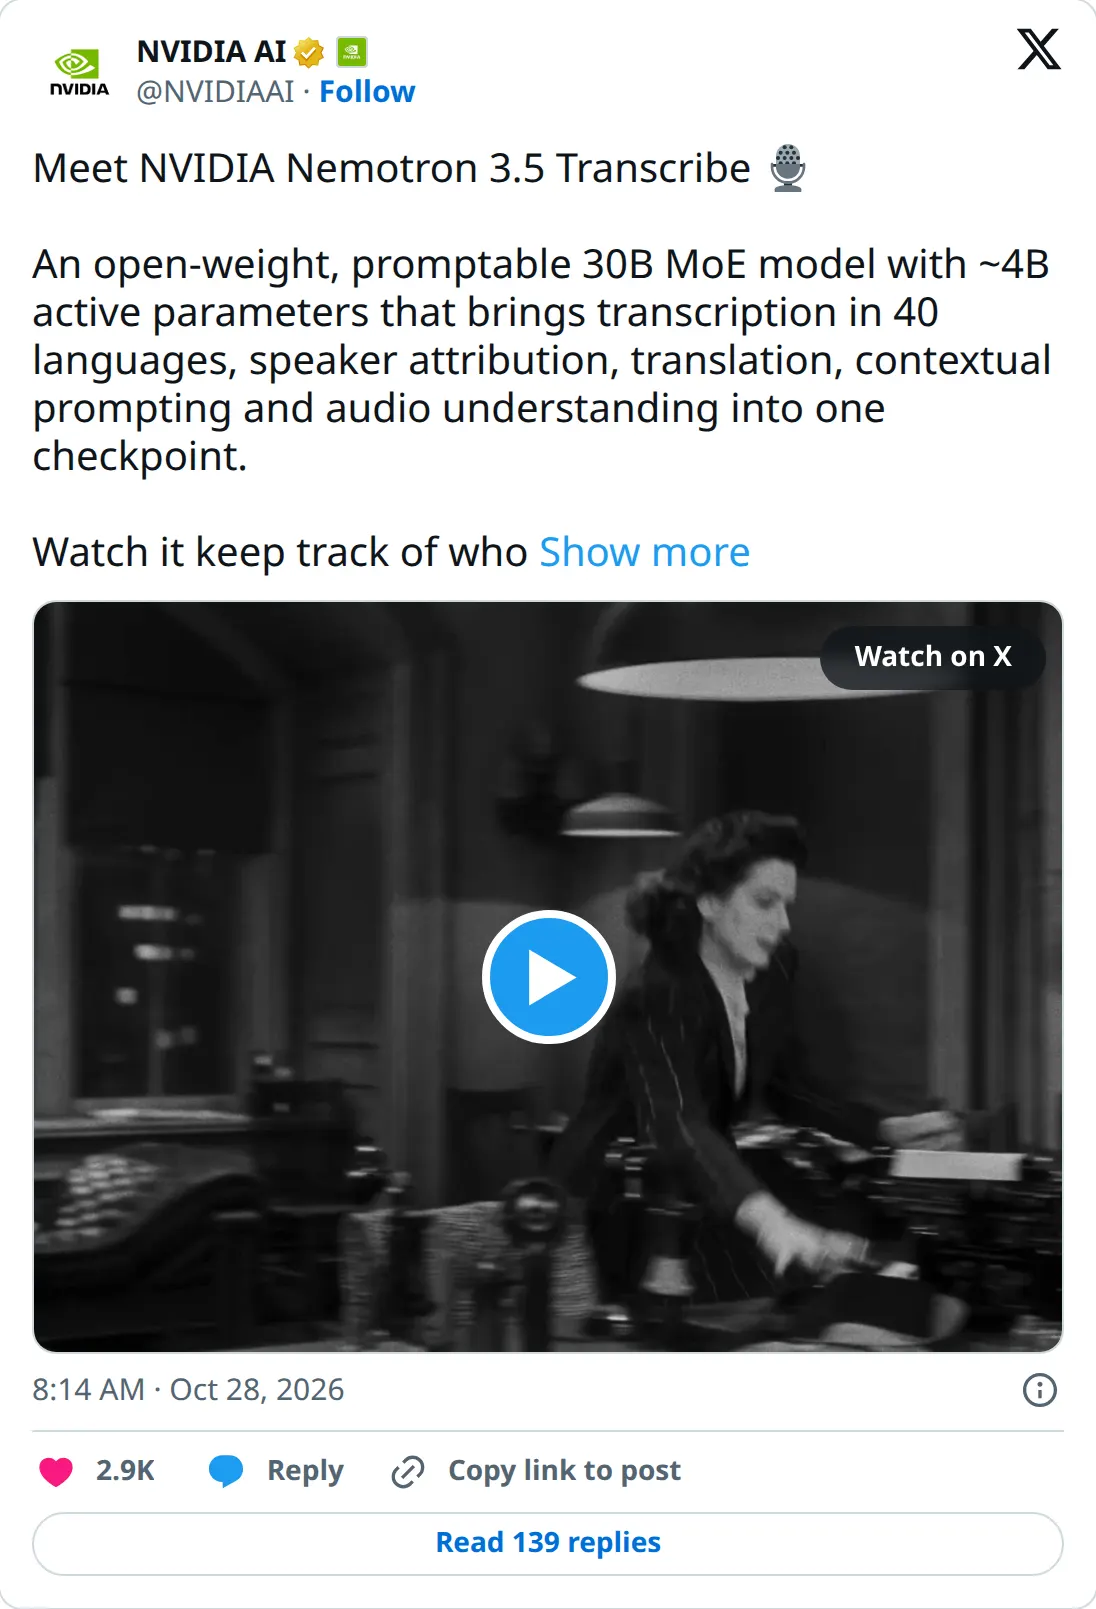
One model handles transcription, translation to or from English in 31 languages, and labeling who's speaking in 13 languages, for recordings up to an hour with up to eight speakers. You can also give it context, such as names or terms, and ask questions about the audio (Hugging Face blog, NVIDIA AI on X).
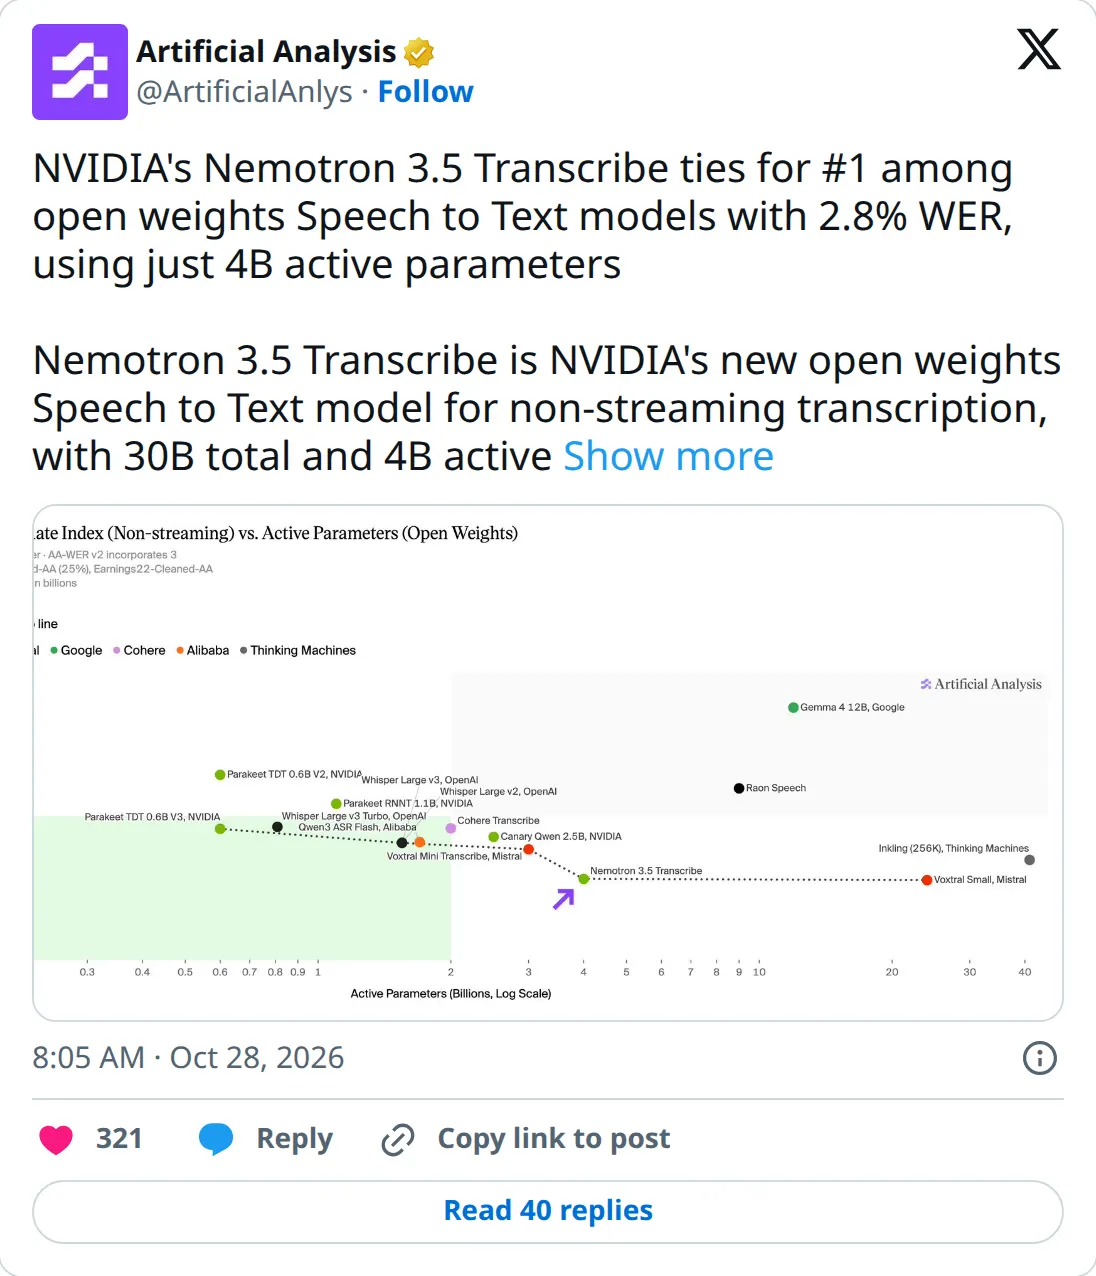
It's a mixture-of-experts model with about 4 billion parameters active at a time. NVIDIA says it ranks first among open-weight models on the Open ASR English leaderboard (vendor claim). Artificial Analysis independently has it tied for #1 among open-weight speech-to-text models, with a 2.8% word error rate (Artificial Analysis on X).
The weights are on Hugging Face under the OpenMDW-1.1 license, and the model card says it's ready for commercial or non-commercial use (model card). It works on recorded audio, not live streams. NVIDIA says smaller quantized versions for running it locally on its own hardware are "coming soon."
What this means for you: if you transcribe meetings, interviews or videos, there's a strong new free option you can try in the Hugging Face demo or through hosted providers. Running it yourself still takes a big GPU until the smaller builds arrive. As NVIDIA itself advises, spot-check names and speaker changes against the recording.
Affiliate disclosure: some stories use affiliate or referral links. When a link pays a commission, the sentence next to it says so. Sponsored slots are labeled Sponsored. The channel card is a house ad until a sponsor is booked.
Newsletter
Join the waitlist and we'll email you when the first issue launches.
By submitting you agree to our Privacy Policy.
You're on the list after you confirm. We'll email you when the newsletter launches. You can leave from any message. The form posts to Resend.