
A fork in the forest track. Photo by Ann Cook, CC BY-SA 2.0, via Wikimedia Commons.

News
OpenAI's Decisions API is now open to all developers, charging only for input at $0.10 per million tokens.
OpenAI's Decisions API is generally available. It costs $0.10 per million input tokens and does not charge for output.
On Thursday, Oct 22, OpenAI made its Decisions API generally available, after a public beta that started earlier this month (OpenAI). It's built for the many small yes-or-no and pick-one questions apps and agents face all day, like how to label a message, where to route a request or what to do next. You write a question and its allowed answers, pass in text, images or JSON data, and get back one of three answer types: a probability that something is true, a choice from your list, or a score on a scale you define. OpenAI says it runs on GPT-6 Luna and answers up to 10x faster than asking GPT-6 Luna the same thing through its regular Responses API.
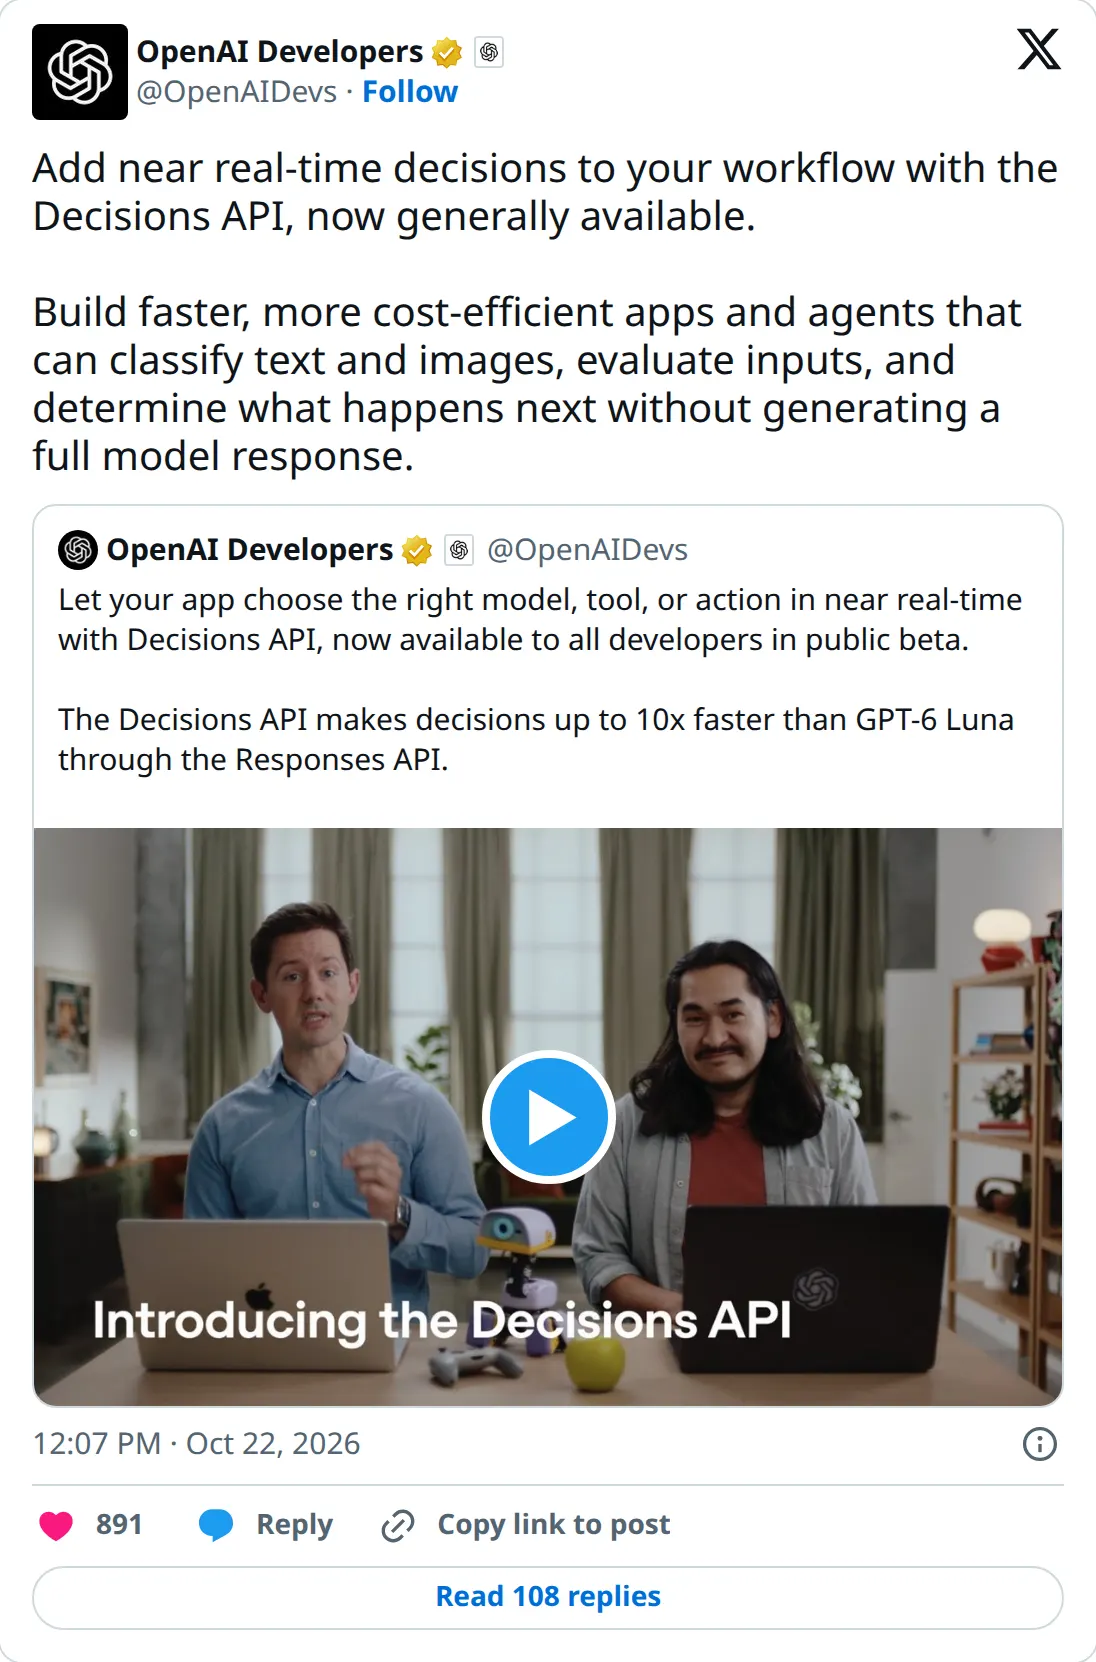
Since the beta, OpenAI has added prompt caching, a hookup to its GPT-Live voice model, data processing inside the US or EU, images in the question instructions, and up to 400 questions per request, double the old limit. It costs $0.10 per million input tokens and $0.01 per million cached input tokens, with no charge for output.
Companies quoted in the post report gains from their own tests: Sierra says it picks the next step in live customer conversations in under 280 milliseconds at 90% lower cost per call, and Speak says reaction time in its language lessons fell from 1.4 seconds to 0.13 seconds (OpenAI Developers on X).
What to weigh: if your app or agent makes lots of simple calls, like sorting messages or choosing the next step, this can be much cheaper and faster than a full chat model. It only answers bounded questions, so anything that needs written output still needs a regular model.
Affiliate disclosure: some stories use affiliate or referral links. When a link pays a commission, the sentence next to it says so. Sponsored slots are labeled Sponsored. The channel card is a house ad until a sponsor is booked.
Newsletter
Join the waitlist and we'll email you when the first issue launches.
By submitting you agree to our Privacy Policy.
You're on the list after you confirm. We'll email you when the newsletter launches. You can leave from any message. The form posts to Resend.